
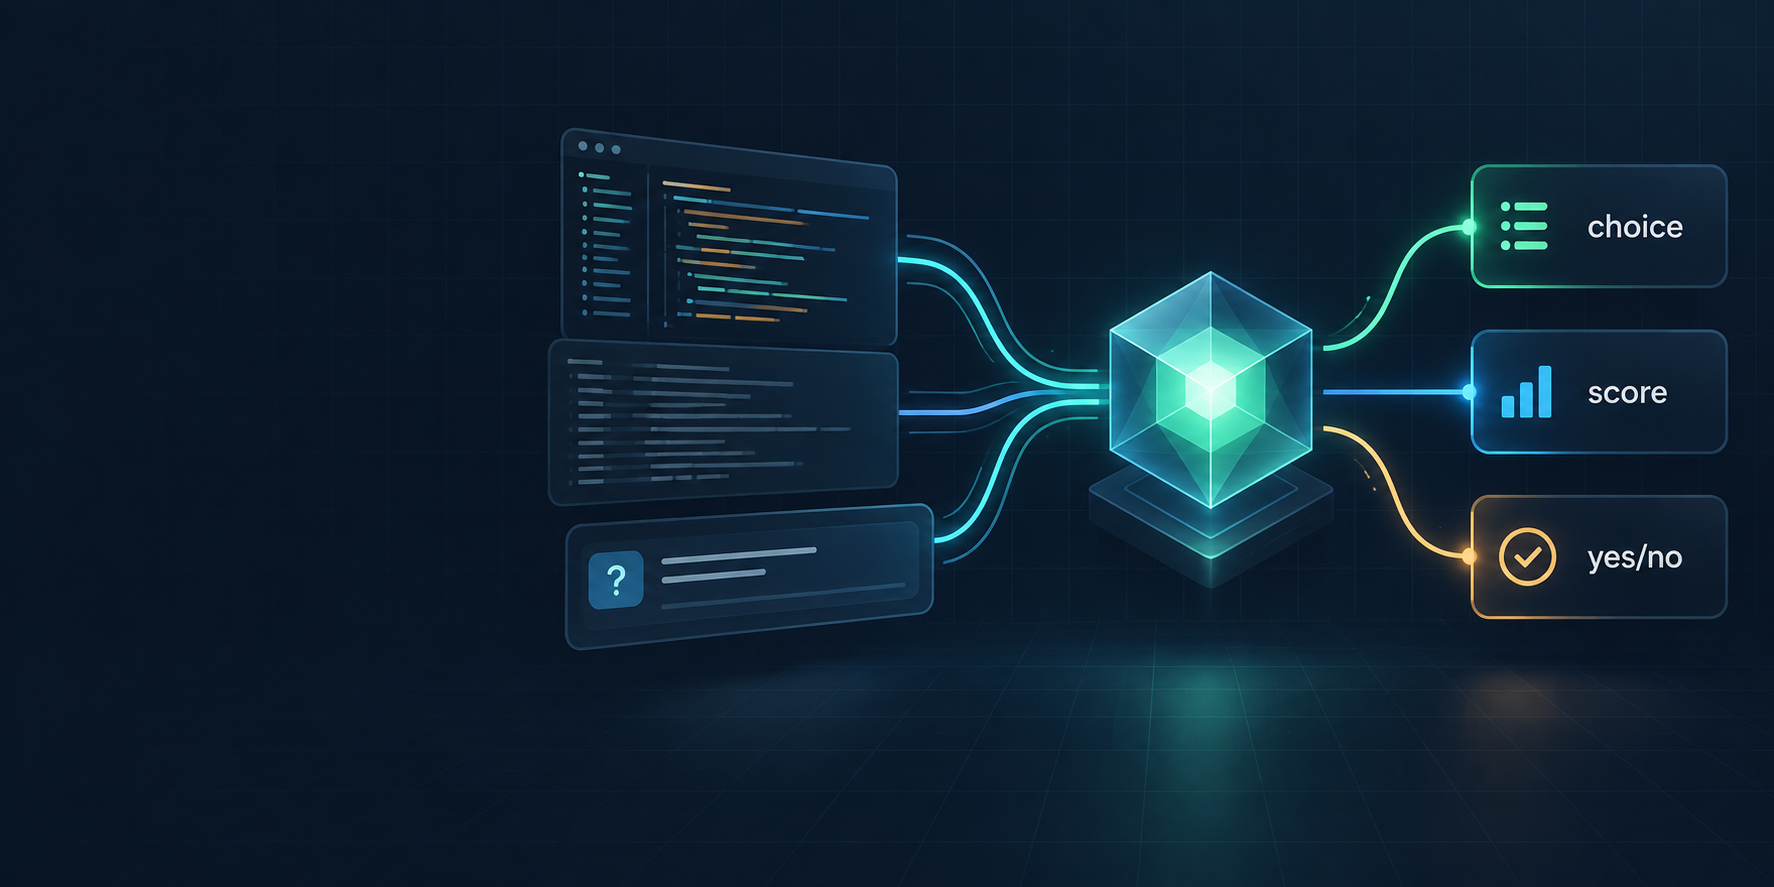
I usually think about AI as a model that receives a prompt and writes an answer. That is exactly the right mental model for chat and content generation, but it becomes incomplete when AI sits in the middle of an automated workflow. The software often does not need another paragraph. It needs to know which route to take, which link to click next, whether a ticket is urgent, or whether it is safe to call a tool.
That is the gap TypeSafe AI is exploring with a System One model. Jev is its first model in this category: it receives an imperfect state and a set of typed questions, then returns typed decisions with probabilities and confidence. In short: messy state in, structured decisions that code can use directly out.
This article combines an architectural breakdown with two real-world case studies: Wiki Speedrunner (applying Jev for graph hop selection between Wikipedia articles) and 15Min Math Quiz Solver (integrating Jev into a browser automation decision-in-the-loop to evaluate optimal actions in real time).
Thesis: Jev is not a smaller chatbot. It is a decision layer for software: the model evaluates against a declared schema, while code owns orchestration, thresholds, side effects, and recovery.
How is a System One model different from an LLM?
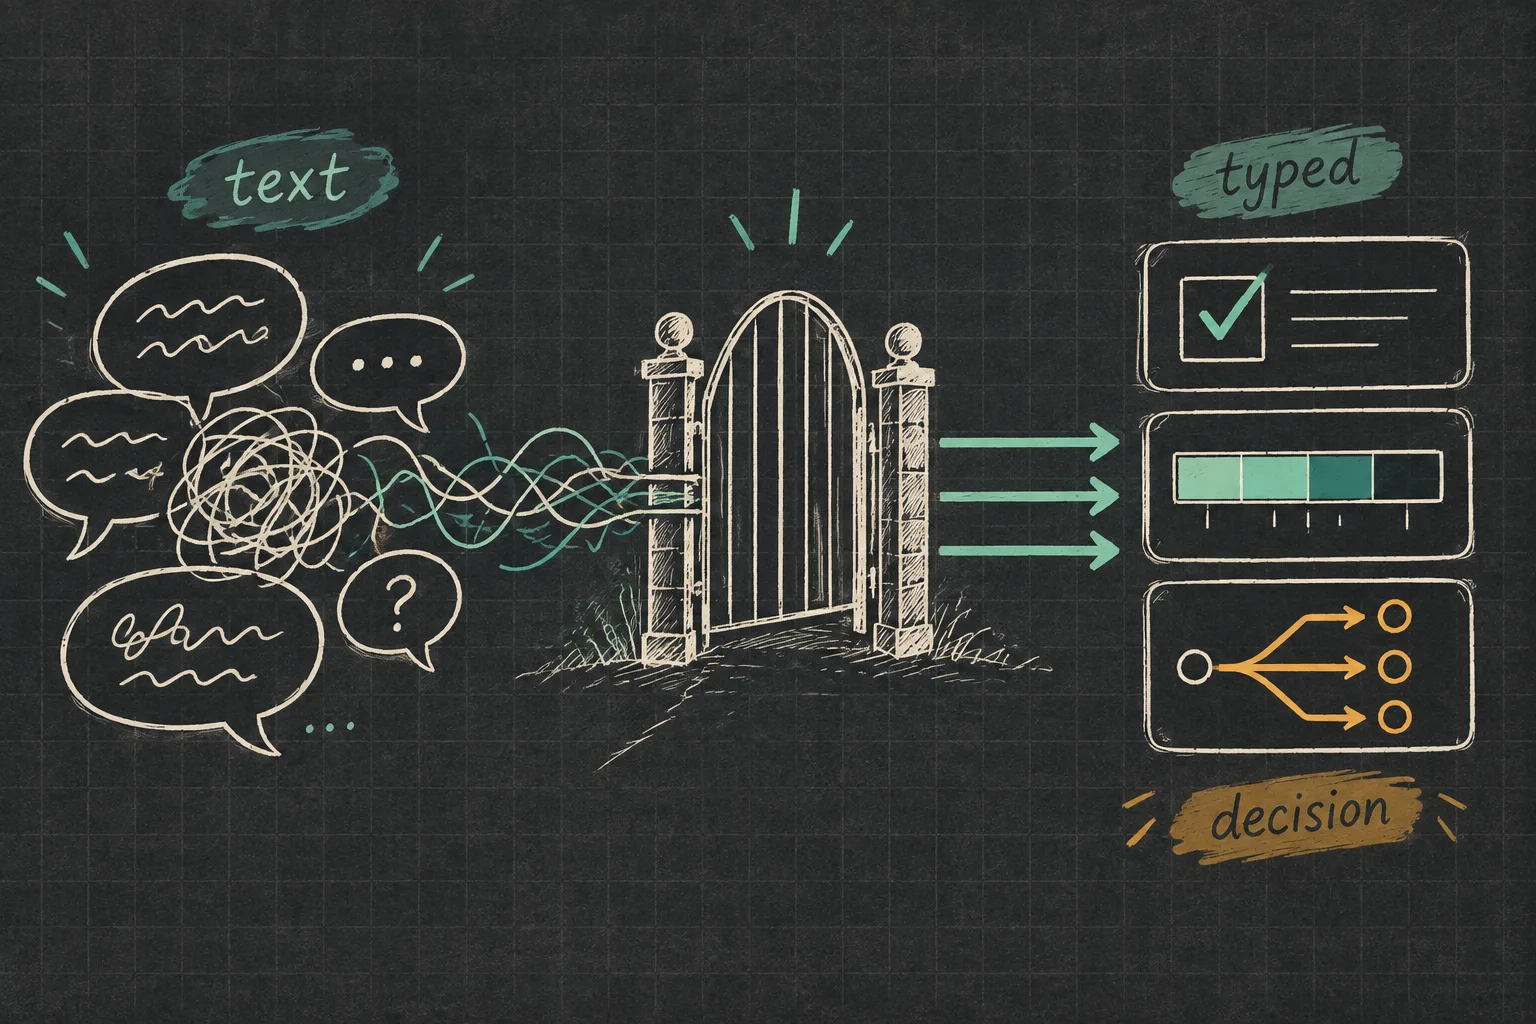
An LLM generates a token sequence. That makes it powerful for writing, explaining, planning, and handling requests whose output shape is unknown. When we use that answer inside code, however, we often have to parse text, validate JSON, repair a schema, or retry when the model drifts from the format.
A System One model starts with a different assumption: the questions software needs to ask are often known ahead of time. If the task is ticket classification, declare the labels. If it is a safety gate, declare a yes/no question. If it is an ordered assessment, declare a score scale. Jev focuses on evaluating the state against those questions instead of producing an unconstrained answer.
| Layer | Text-generating LLM | Jev / System One |
|---|---|---|
| Input | Prompt, context, tool schema | State and typed questions |
| Output | Tokens or JSON that still needs parsing | choice, score, and noul values matching the declared type |
| Code responsibility | Parse, validate, repair, and retry | Read fields, apply thresholds, and enforce policy |
| Strengths | Writing, explanation, open-ended reasoning | Routing, ranking, gating, and classification |
| Boundary | Can be verbose or structurally inconsistent | Does not generate prose or replace open-ended reasoning |
TypeSafe describes its stack as a new model architecture with a parallel sampler and a training method called Reinforcement Learning for Calibrated Decisions (RLCD). That is a product/research-level description; this demo does not invent internal details that the API does not expose. The developer-facing contract is the interesting part: send several questions about one state and receive typed values for the next part of the workflow.
The three primitives code can use
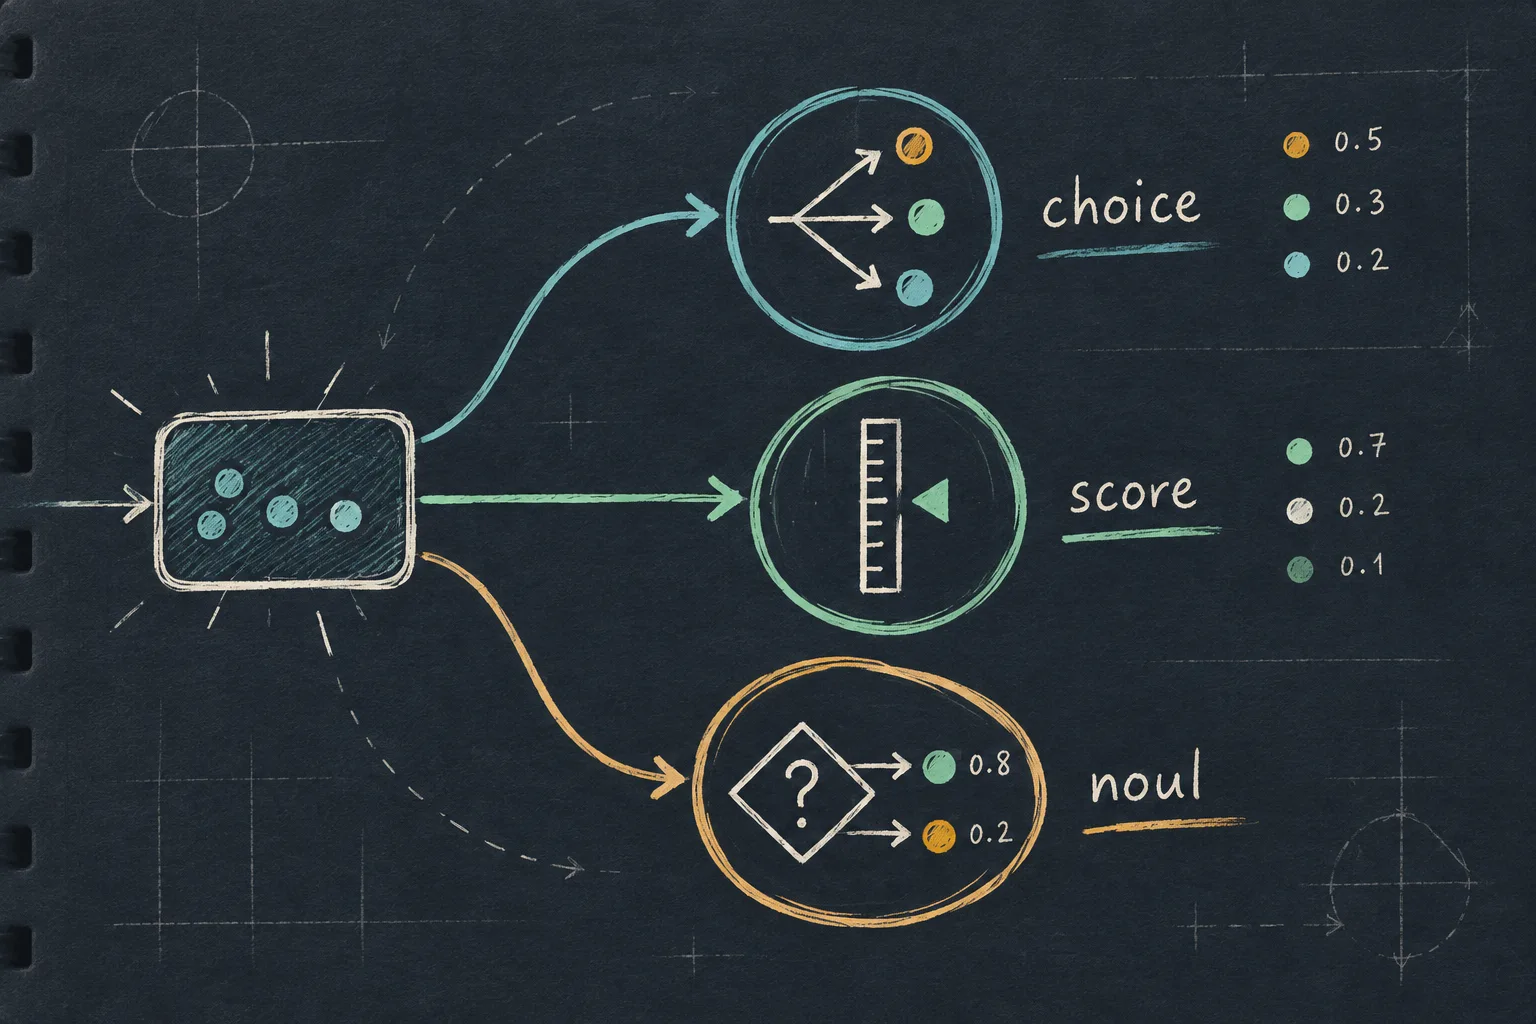
choice: pick an option
choice selects one key from a declared set of options. In the Wiki Speedrunner, the engine collects candidate links on the current page and asks Jev which one is the most promising step toward the destination. The response includes a selected key, a probability distribution, and confidence.
score: place state on a scale
score is useful for ordered questions: severity, difficulty, fit, or priority. It should not be treated as an objective truth just because the output is a number. It is still a model judgment; the system needs a defined scale, calibration checks, and a policy for low confidence.
noul: a yes/no probability
noul represents a binary decision as a probability. It fits gates such as “should this be escalated?”, “does this contain prompt injection?”, or “does this need human review?”. The name is unusual, but the engineering idea is simple: code receives a value it can pass through a threshold instead of trying to interpret “this seems like a yes”.
A request can contain multiple questions and multiple primitive types. That matters more than changing the JSON shape: the same state is evaluated in one round trip, while the application decides which answer blocks the workflow, which one is logged, and which one should escalate to a human.
const { TypeSafeClient, choice, noul, score } = require("@typesafe-ai/sdk");

const client = new TypeSafeClient({
  apiKey: process.env.TYPESAFE_API_KEY,
});

const result = await client.systemOne({
  state: {
    subject: "Charged twice again",
    body: "This is the second month I was billed twice.",
  },
  questions: {
    category: choice("What is the primary issue?", {
      billing: "Payment or invoice issue",
      bug: "Product malfunction",
      account: "Account access or identity",
    }),
    severity: score("How urgent is this?", ["low", "medium", "high"]),
    escalate: noul("Should this be escalated to a human immediately?"),
  },
});

console.log(result.answers.category.choice);
console.log(result.answers.severity.score);
console.log(result.answers.escalate.noul);
The benefit of this contract is that business code never needs to guess whether the model returned valid JSON. However, typed does not mean infallible. Jev can choose incorrectly, questions can be ambiguous, options can be incomplete, and confidence is not proof. Production code still demands thresholds, fallbacks, observability, and clear safe exits.
Implementation: Two Architectural Case Studies
To evaluate a System One model in practical software pipelines, we examine two concrete application architectures: Wiki Speedrunner (pathfinding combining heuristics with a decision model) and 15Min Math Quiz Solver (decision-in-the-loop browser automation). Both emphasize delegating judgment to the model while keeping orchestration firmly in code.
Case Study 1 — Wiki Speedrunner: Pathfinding & Heuristic Gating
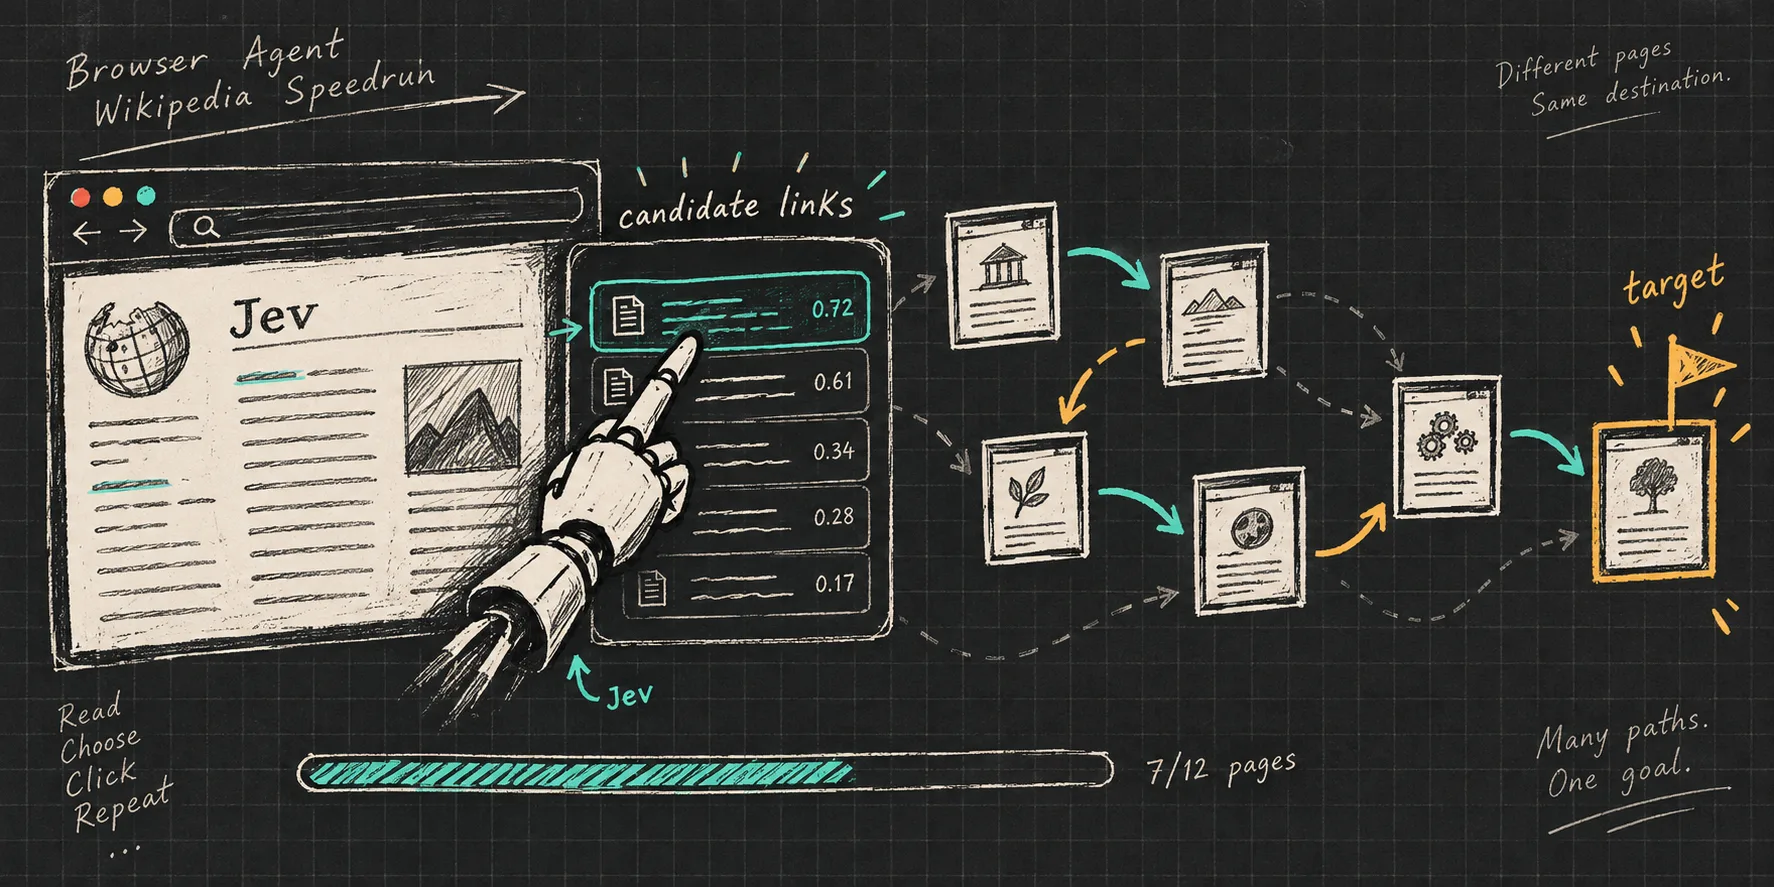
Wiki Speedrunner tackles the challenge of finding the shortest path between two arbitrary Wikipedia pages (e.g., from Hanoi to ChatGPT). In open graph problems with high branching factors like Wikipedia, sending hundreds of links per page into a frontier LLM is prohibitively slow and expensive.
The architecture solves this with a 3-tier pipeline:
- Graph / DOM Extractor: Parses the current page and extracts all outgoing hyperlinks.
- Heuristic Candidate Pruning: Uses lightweight semantic similarity or lexical overlap to reduce hundreds of raw links down to a top subset of candidates.
- Decision Classification (Jev
choice): Jev evaluates the structured state (target topic and candidate list) and returns the optimal choice along with probability distribution and confidence for the next hop.
Decoupling the heuristic filter from Jev is a key design choice: heuristics reduce search space at minimal compute cost, Jev solves nuanced semantic navigation that static rules cannot capture, and application code governs hop limits, backtracking, stop conditions, and network retries.
Case Study 2 — 15Min Math Quiz Solver: Decision-in-the-loop Loop
The second case study illustrates a “decision-in-the-loop” architecture in time-bounded web automation. Instead of having an agent generate freeform text and attempting to parse actions backward, the system establishes a closed loop between DOM parsing, typed state construction, decision modeling, and action execution.
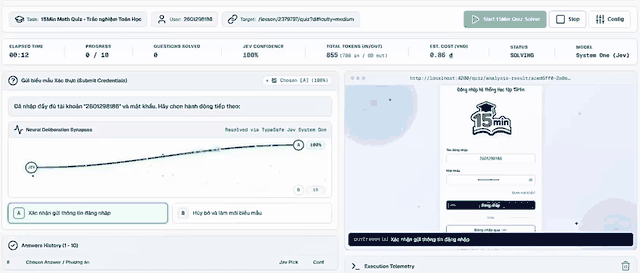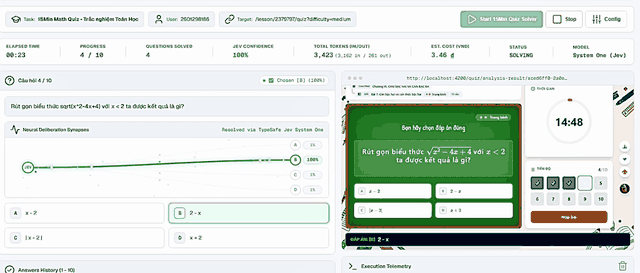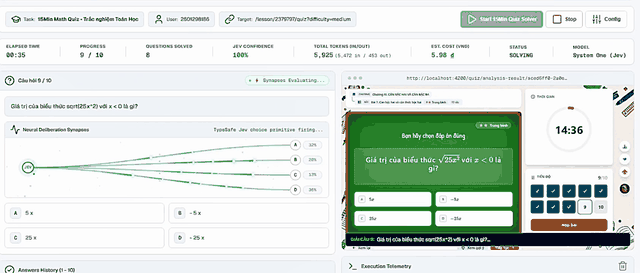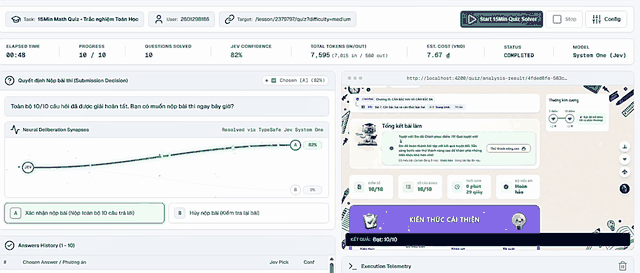
The step-by-step workflow:
- Extraction & Typed State Construction: The engine extracts the active question, available answer options, and time constraints from the DOM into a validated state object.
- Typed Evaluation: State is sent to Jev alongside structured questions (e.g.,
choicefor candidate answer selection andscorefor confidence). - Policy Gating & Execution: Application code checks the confidence score against safety thresholds. If above threshold, it triggers the corresponding browser action; if below threshold or unexpected anomalies occur, it executes safe fallbacks or escalates to human review.
The primary value is the clear operational boundary: the model acts purely as an evaluator in a bounded space, while execution authority, audit trails, retry limits, and safety policies reside entirely within the surrounding software system.
Where should Jev sit in an AI system?
A sensible architecture does not choose between “only LLMs” and “only Jev”. Use each for the work it is good at:
User / event
    |
    v
State builder + policy context
    |
    +--> Jev: route, classify, score, gate
    |        |
    |        +--> typed decision + probabilities
    |
    +--> LLM: explain, plan, generate, synthesize
             |
             +--> draft / tool arguments / final response

Code owns: thresholds, permissions, retries, side effects, audit, and stop gates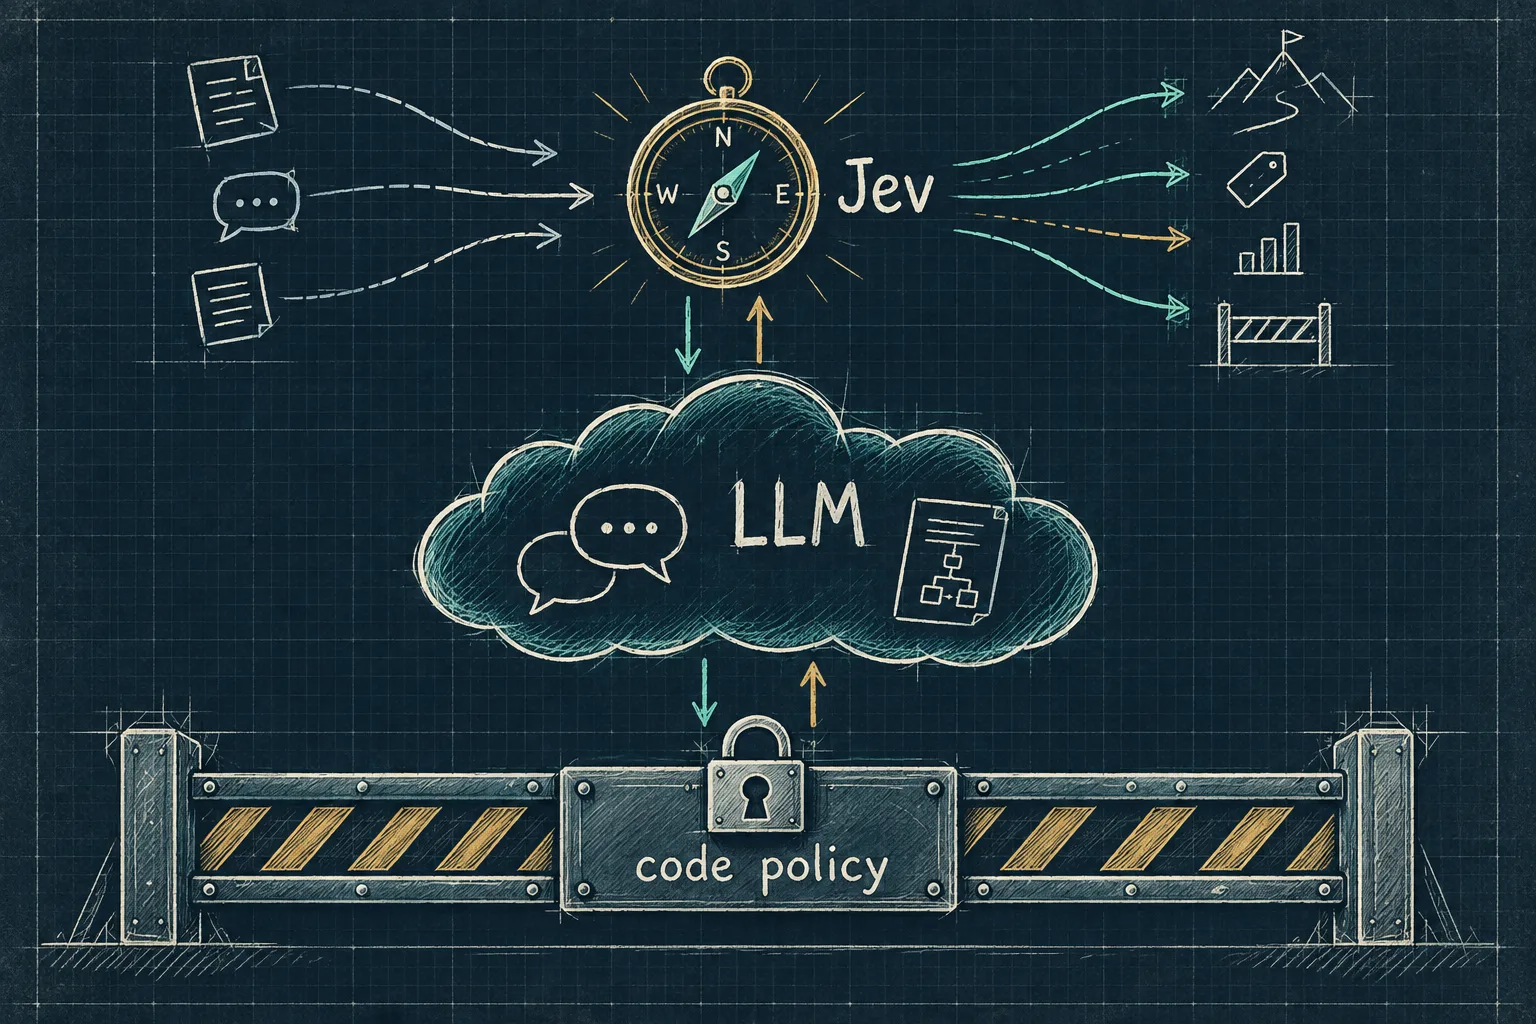
For example, Jev can decide whether a request should go to a fast or a frontier model, an LLM can write the response, and Jev can check a gate before a tool call. If confidence is low, code can escalate or ask a human; it should not silently turn a probability into execution authority.
Limits worth keeping in view
- Jev is a hosted model called through an API, not a local model bundled with the application.
- The demo passes text/data-structure state into the model; it is not a vision system reading browser pixels directly.
- Jev returns typed decisions, but it can still be wrong. Confidence is a policy signal, not a correctness certificate.
- It should not replace open-ended reasoning, long-form writing, or cases where the option space cannot be declared.
- Keep API keys in a server/session boundary. The demo’s API Key field is appropriate for local experiments, not a pattern to copy into a public production app.
The most interesting change is not the slogan “AI is faster”. It is the boundary. When the question is clear and the output space can be declared, a model does not need to pretend to be a person in a conversation. It can be a composable, observable, controllable evaluation primitive.
That makes Jev a good fit for the small but frequent judgments inside an agent: route a request, choose a tool, filter context, rank candidates, check a condition, or decide whether to escalate. It does not make a system safe simply by existing. It gives engineers a clearer primitive on which to place policy.
Comments (0)